Papers
Neural Machine Translation by jointly learning to Align and Translate
How Bahdanau et al. (2014) replaced the fixed-length context vector with soft attention, the paper that introduced the attention mechanism.
Introduction
This paper is mainly about attention, this is the first paper that applies Attention to the Neural Machine Translation(NLP in general)
Outline
- Task definition
- Basic RNN Encoder-Decoder and issues related to it
- Align and Translate (attention)
- Bidirectional RNN
- Experiments and Results
The Task
X is the source language where Y is the target language Kx is the vocabulary size of source language where Kx is the the vocabulary size for target language
I want to maximized the probability of target language sentence conditioned on the source language sentence
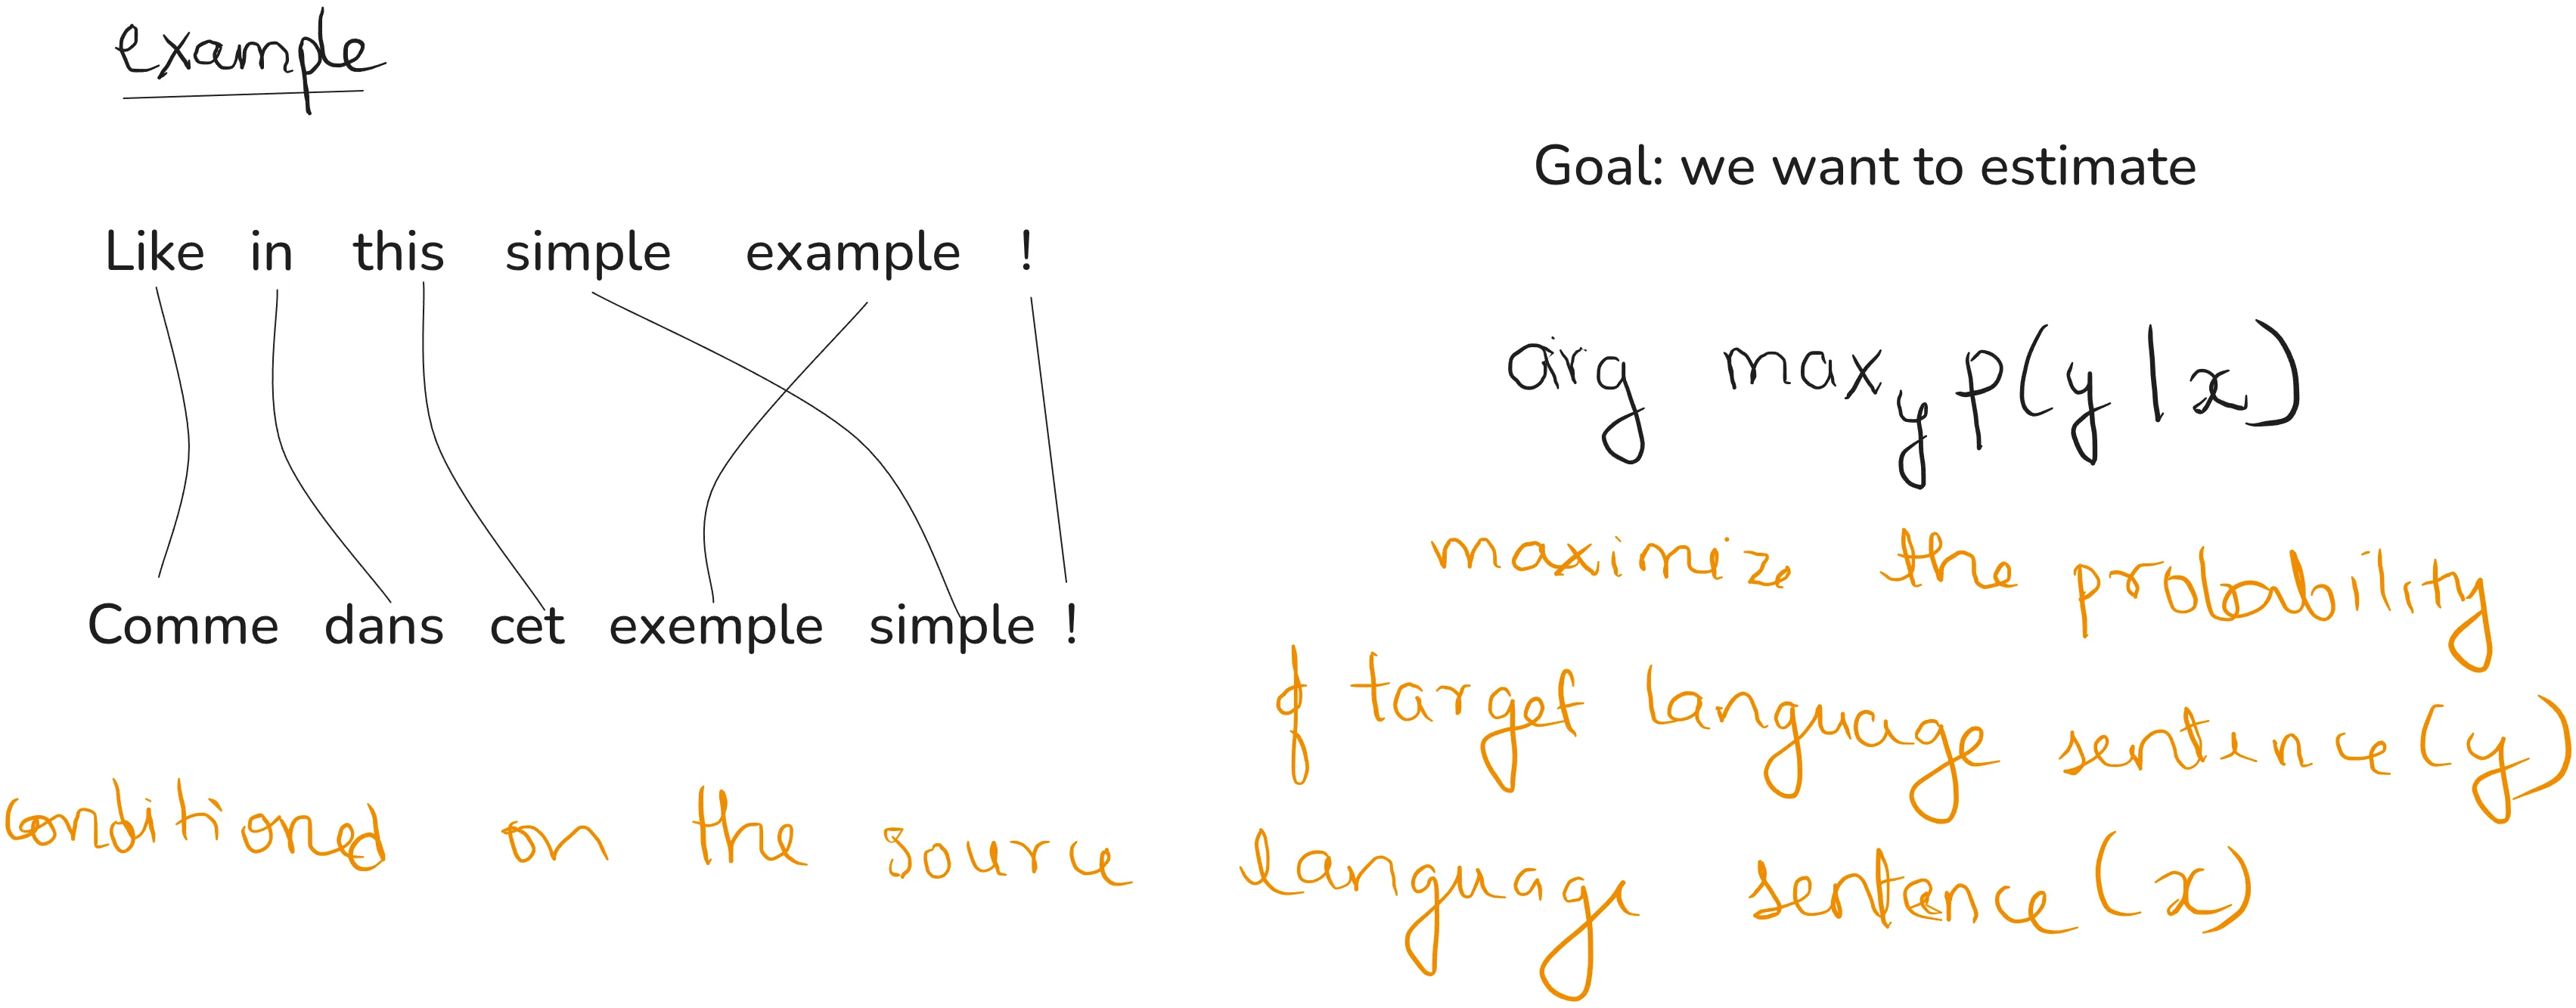
Source input for each instance has variable length and target sentence may or may not have the same length
RNN Encoder-decoder (baseline)
Components
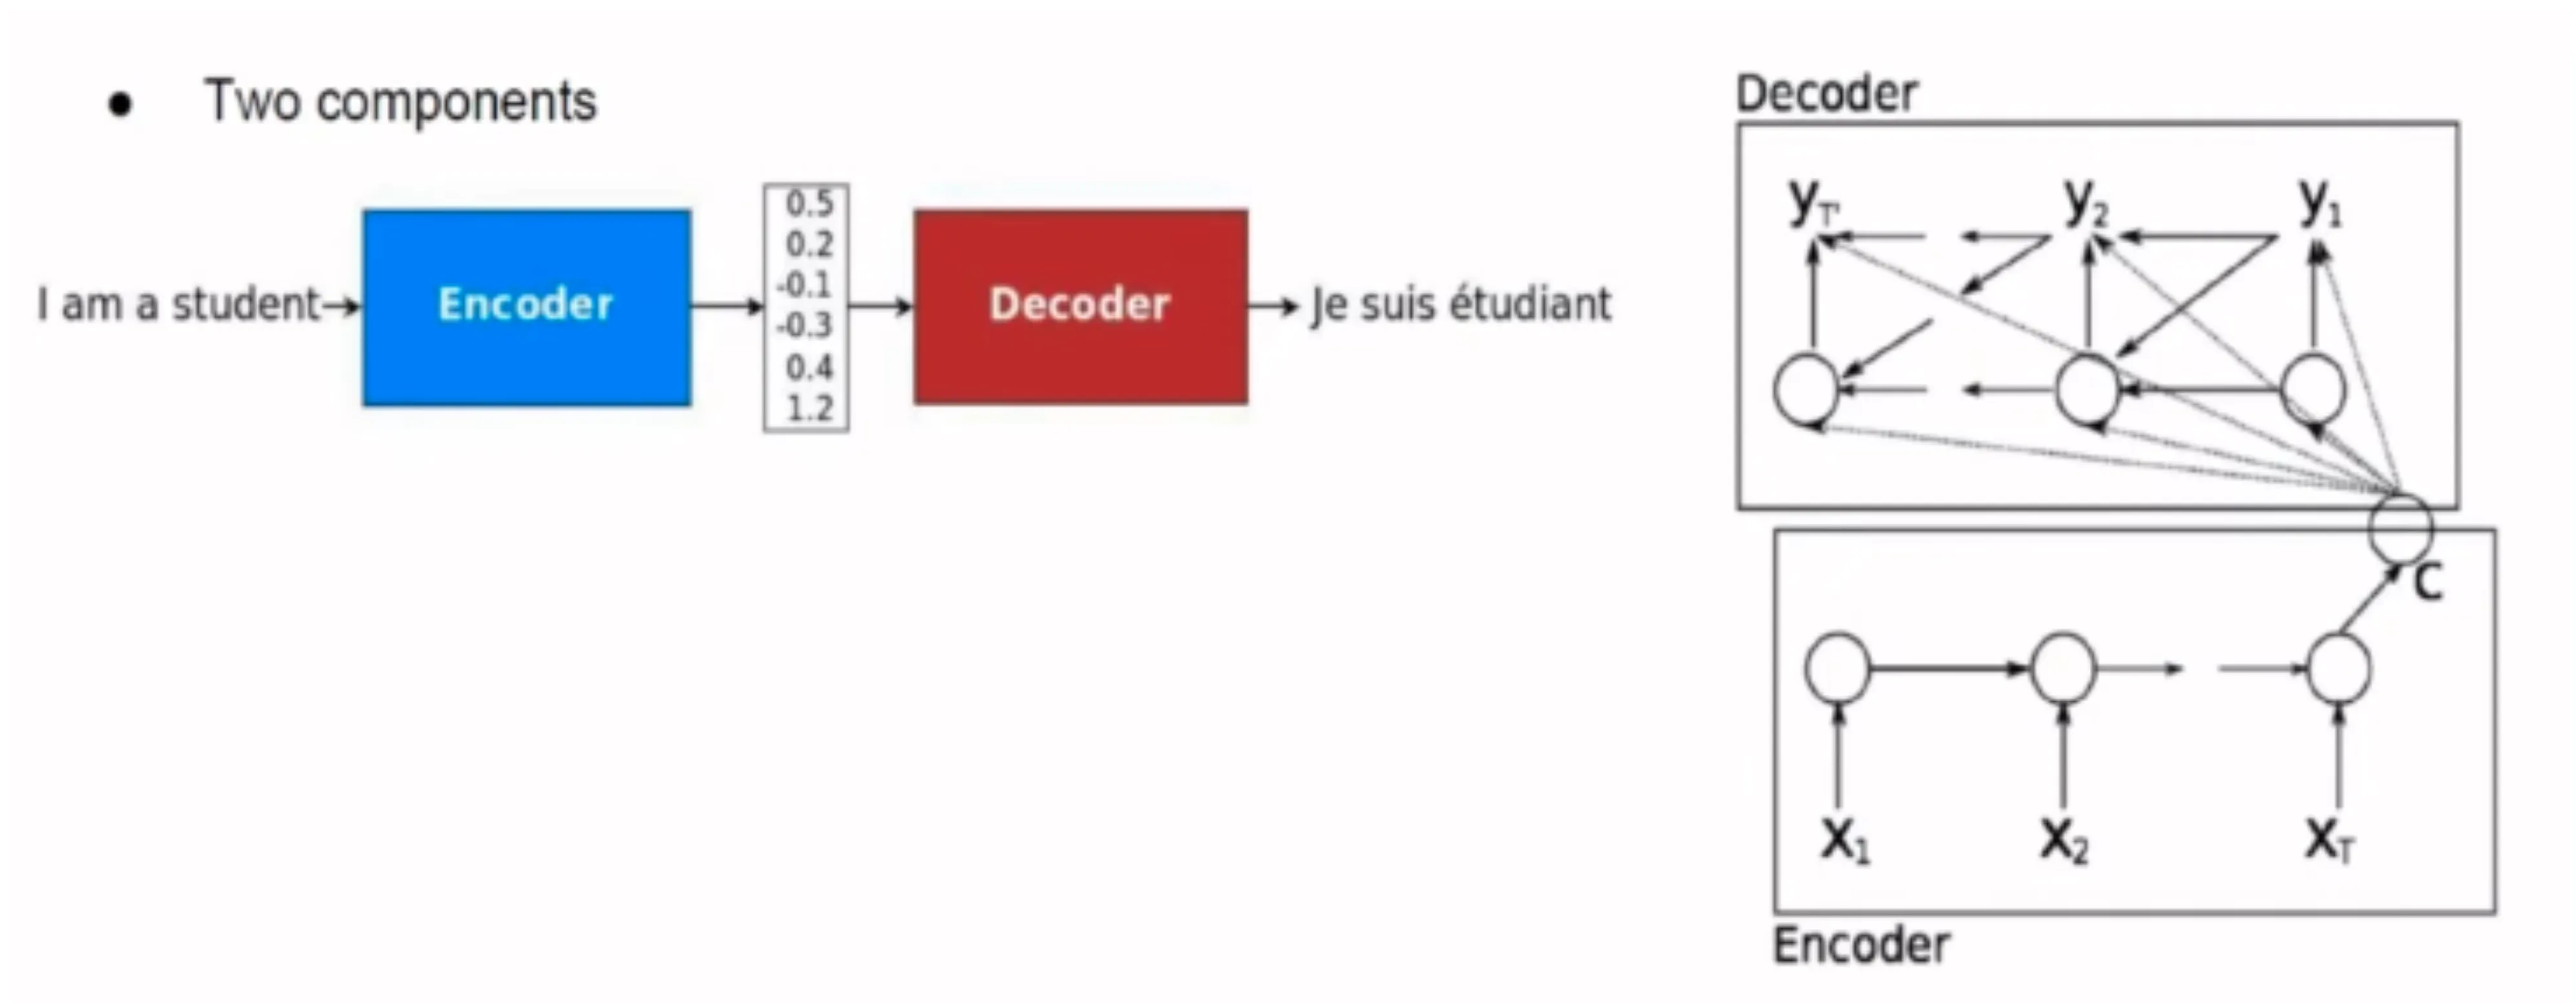
- Basic idea is
Wrapping up
Delete this template content and write your own. When it’s ready, set
draft: false in the frontmatter above, then commit and push.